Base class for Ito diffusion particle models. More...
#include <CD_ItoSolver.H>
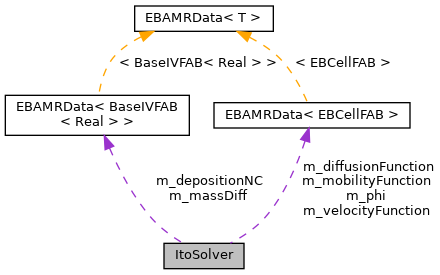
Public Types | |
| enum class | WhichContainer { Bulk , EB , Domain , Source , Covered , Scratch } |
| Enum class for distinguishing various types of particle containers. More... | |
Public Member Functions | |
| ItoSolver () | |
| Constructor – user must subsequently set the realm and, parse class options, set the species etc. | |
| virtual | ~ItoSolver () |
| Destructor (does nothing). | |
| ItoSolver (const ItoSolver &)=delete | |
| Deleted copy constructor. | |
| ItoSolver & | operator= (const ItoSolver &)=delete |
| Deleted copy assignment operator. | |
| ItoSolver (ItoSolver &&)=default | |
| Default move constructor. | |
| ItoSolver & | operator= (ItoSolver &&)=default |
| Default move assignment operator. | |
| virtual void | setParticleCellMerger (const ParticleManagement::ParticleMerger< ItoMergeParticle > &a_particleCellMerger) noexcept |
| Set the user-supplied per-cell particle merger used by merge_method = external. | |
| virtual std::string | getName () const |
| Get this solver's name. | |
| virtual std::string | getRealm () const |
| Get the realm where this solver is registered. | |
| virtual void | setRealm (const std::string &a_realm) |
| Set the realm where this solver will live. | |
| virtual void | parseOptions () |
| Parse class options. | |
| virtual void | parseRuntimeOptions () |
| Parse class runtime configurable options. | |
| virtual EBIntersection | getIntersectionAlgorithm () const noexcept |
| Get the EB-particle intersection algorithm. | |
| virtual Real | getBisectionStep () const noexcept |
| Get the path-march length used by the bisection intersection algorithm. | |
| virtual void | initialData () |
| Set the initial data. | |
| virtual void | generateParticlesFromDensity (ParticleContainer< ItoParticle > &a_particles, const std::function< Real(const RealVect x)> &a_densityFunc, const Vector< int > &a_maxParticlesPerCell) const noexcept |
| Fill a particle container randomly with particles such that we obtain the target uniform density, with a per-level cap on the computational particle count. | |
| virtual void | generateParticlesFromDensity (ParticleContainer< ItoParticle > &a_particles, const std::function< Real(const RealVect x)> &a_densityFunc, int a_maxParticlesPerCell) const noexcept |
| Fill a particle container randomly with particles such that we obtain the target uniform density. | |
| virtual void | regrid (int a_lmin, int a_oldFinestLevel, int a_newFinestLevel) |
| Regrid this solver. | |
| virtual void | allocate () |
| Allocate internal storage. | |
| virtual void | clear (WhichContainer a_container) |
| Clear a particle container – this will delete all the particles in the input container. | |
| virtual void | clear (ParticleContainer< ItoParticle > &a_particles) const |
| Clear a particle container – this will delete all the particles in the input container. | |
| virtual void | depositConductivity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Deposit conductivities (i.e. mass*mobility / volume) | |
| virtual void | depositConductivity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles, DepositionType a_deposition, CoarseFineDeposition a_coarseFineDeposition) const |
| Deposit conductivities (i.e. mass*mobility / volume) | |
| virtual void | depositDiffusivity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Deposit diffusivity (i.e. mass*D/volume) | |
| virtual void | depositDiffusivity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles, DepositionType a_deposition, CoarseFineDeposition a_coarseFineDeposition) const |
| Deposit diffusivity (i.e. mass*D/volume) | |
| virtual void | depositEnergyDensity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Deposit energy densities (i.e. mass*energy/volume => total energy per unit volume) | |
| virtual void | depositEnergyDensity (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles, DepositionType a_deposition, CoarseFineDeposition a_coarseFineDeposition) const |
| Deposit energy densities (i.e. mass*energy/volume => total energy per unit volume) | |
| virtual void | computeAverageMobility (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Compute average mobility. | |
| virtual void | computeAverageDiffusion (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Compute average diffusion coefficient. | |
| virtual void | computeAverageEnergy (EBAMRCellData &a_phi, ParticleContainer< ItoParticle > &a_particles) const |
| Compute average particle energy.. | |
| virtual void | depositParticles () |
| Deposit particles onto mesh. | |
| virtual void | depositParticles (WhichContainer a_container) |
| Deposit particles on to mesh. | |
| void | depositWeightNGP (LevelData< EBCellFAB > &a_output, const ParticleContainer< ItoParticle > &a_particles, int a_level) const noexcept |
| Do an NGP deposit of the SoA weight column on a specific grid level. Used for IO. | |
| template<typename Gather > | |
| void | depositGatheredNGP (LevelData< EBCellFAB > &a_output, const ParticleContainer< ItoParticle > &a_particles, int a_level, Gather a_gather) const noexcept |
| Do an NGP deposit of a gathered per-particle quantity on a specific grid level. Used for IO. | |
| void | coarsenAndFillGhosts (EBAMRCellData &a_phi) const |
| Coarsen the input data and interpolate its ghost cells. | |
| template<typename P , typename Traits > | |
| void | depositWeight (EBAMRCellData &a_phi, const ParticleContainer< P, Traits > &a_particles, DepositionType a_deposition, CoarseFineDeposition a_coarseFineDeposition) const |
| Deposit the SoA weight column on the mesh (kappa-conservative + redistribution). | |
| template<typename Gather > | |
| void | depositGathered (EBAMRCellData &a_phi, const ParticleContainer< ItoParticle > &a_particles, DepositionType a_deposition, CoarseFineDeposition a_coarseFineDeposition, Gather a_gather) const |
| Deposit a gathered per-particle quantity on the mesh (kappa-conservative + redistribution). | |
| template<typename P , typename Traits , typename Strength > | |
| void | mirrorPass (EBAMRCellData &a_phi, const ParticleContainer< P, Traits > &a_particles, const DepositionType a_deposition, const CoarseFineDeposition a_coarseFineDeposition, const Strength a_strength) const |
| Add the mirrored contribution of the band particles to an already-deposited field. | |
| virtual void | removeCoveredParticles (EBRepresentation a_representation, Real a_tol) |
| Remove particles that are inside the EB. | |
| virtual void | removeCoveredParticles (WhichContainer a_container, EBRepresentation a_representation, Real a_tol) |
| Remove particles that are inside the EB. | |
| virtual void | removeCoveredParticles (ParticleContainer< ItoParticle > &a_particles, EBRepresentation a_representation, Real a_tol) const |
| Remove particles that are inside the EB. | |
| virtual void | transferCoveredParticles (EBRepresentation a_representation, Real a_tol) |
| Transfer particles that are covered (within a_tol distance from EB) to another container. | |
| virtual void | transferCoveredParticles (WhichContainer a_containerFrom, WhichContainer a_containerTo, EBRepresentation a_representation, Real a_tol) |
| Transfer particles that are covered (within a_tol distance from EB) to another container. | |
| virtual void | transferCoveredParticles (ParticleContainer< ItoParticle > &a_particlesFrom, ParticleContainer< ItoParticle > &a_particlesTo, EBRepresentation a_representation, Real a_tol) const |
| Transfer particles that are inside the EB to another container. | |
| virtual void | intersectParticles (const EBIntersection a_ebIntersection, const bool a_deleteParticles, const std::function< void(ParticleSoA< ItoParticle > &, std::size_t)> &a_nonDeletionModifier=[](ParticleSoA< ItoParticle > &, std::size_t) -> void { return;}) |
| Do boundary intersection tests. | |
| virtual void | intersectParticles (const WhichContainer a_particles, const WhichContainer a_ebParticles, const WhichContainer a_domainParticles, const EBIntersection a_ebIntersection, const bool a_deleteParticles, const std::function< void(ParticleSoA< ItoParticle > &, std::size_t)> &a_nonDeletionModifier=[](ParticleSoA< ItoParticle > &, std::size_t) -> void { return;}) |
| Do boundary intersection tests. | |
| virtual void | intersectParticles (ParticleContainer< ItoParticle > &a_particles, ParticleContainer< ItoParticle > &a_ebParticles, ParticleContainer< ItoParticle > &a_domainParticles, const EBIntersection a_ebIntersection, const bool a_deleteParticles, const std::function< void(ParticleSoA< ItoParticle > &, std::size_t)> &a_nonDeletionModifier=[](ParticleSoA< ItoParticle > &, std::size_t) -> void { return;}) |
| Do boundary intersection tests. | |
| virtual void | computeLoads (Vector< long int > &a_loads, const DisjointBoxLayout &a_dbl, int a_level) |
| Compute particle load on a specific grid level – this will compute the number of particles in each box in the input grids. | |
| virtual int | getNumberOfPlotVariables () const |
| Get number of plot variables. | |
| virtual Vector< std::string > | getPlotVariableNames () const |
| Get output plot names. | |
| virtual void | writePlotData (LevelData< EBCellFAB > &a_output, int &a_comp, const std::string &a_outputRealm, int a_level) const noexcept |
| Write plot data. | |
| virtual unsigned long long | getNumParticles (WhichContainer a_whichContainer, bool a_localOnly) const |
| Get number of particles in a specified particle container. | |
| virtual void | registerOperators () const |
| Register operators. | |
| virtual void | setComputationalGeometry (const RefCountedPtr< ComputationalGeometry > &a_computationalGeometry) |
| Set computational geometry. | |
| virtual void | setAmr (const RefCountedPtr< AmrMesh > &a_amr) |
| Set the AmrMesh object. | |
| virtual void | setPhase (phase::which_phase a_phase) |
| Set phase where the particles will live. | |
| virtual void | setVerbosity (int a_verbosity) |
| Set verbosity level for this solver. | |
| virtual void | setTime (int a_step, Real a_time, Real a_dt) |
| Set the time for this solver. | |
| virtual void | setSpecies (const RefCountedPtr< ItoSpecies > &a_species) |
| Set the species. | |
| virtual void | preRegrid (int a_lbase, int a_oldFinestLevel) |
| Perform pre-regrid operations. | |
| virtual bool | isMobile () const |
| Check if solver is mobile. | |
| virtual bool | isDiffusive () const |
| Check if solver is diffusive. | |
| virtual ParticleContainer< ItoParticle > & | getParticles (WhichContainer a_container) |
| Get a general particle container. | |
| virtual const ParticleContainer< ItoParticle > & | getParticles (WhichContainer a_container) const |
| Get a general particle container. | |
| virtual const RefCountedPtr< ItoSpecies > & | getSpecies () const |
| Get the species. | |
| virtual EBAMRCellData & | getPhi () |
| Get the mesh data. | |
| virtual EBAMRCellData & | getVelocityFunction () |
| Get cell-centered velocity mesh data. | |
| virtual const EBAMRCellData & | getVelocityFunction () const |
| Get cell-centered velocity mesh data. | |
| virtual EBAMRCellData & | getDiffusionFunction () |
| Get the diffusion function. | |
| virtual const EBAMRCellData & | getDiffusionFunction () const |
| Get the diffusion function. | |
| virtual EBAMRCellData & | getMobilityFunction () |
| Get mobility function. | |
| virtual const EBAMRCellData & | getMobilityFunction () const |
| Get mobility function. | |
| virtual void | setDiffusionFunction (Real a_diffusionCoefficient) |
| Utility function – set a constant diffusion coefficient. | |
| virtual void | setVelocityFunction (const RealVect &a_velocity) |
| Utility function – set a constant velocity. | |
| virtual void | setParticleMobility (Real a_mobility) |
| Sets mobility coefficient for all particles. | |
| virtual void | setParticleDiffusion (Real a_diffCo) |
| Sets diffusion coefficient for all particles. | |
| virtual void | interpolateVelocities () |
| Interpolate the particle velocities. | |
| virtual void | interpolateVelocities (int a_lvl, const DataIndex &a_dit) |
| Interpolate the particle velocities. | |
| virtual void | interpolateMobilities () |
| Interpolate mobilities. | |
| virtual void | updateMobilities () |
| Update mobilities parametrically from the particle energy. | |
| virtual void | interpolateDiffusion () |
| Interpolate the diffusion field to the particle positions. | |
| virtual void | computeDiffusionGradient () |
| Compute the cell-centered gradient of the mesh diffusion field. | |
| virtual void | interpolateDiffusionGradient () |
| Interpolate the mesh diffusion gradient onto the particles' scratch vector storage. | |
| virtual void | interpolateDiffusionGradient (int a_lvl, const DataIndex &a_dit) |
| Interpolate the mesh diffusion gradient onto the particles' scratch vector storage, on one patch. | |
| virtual bool | isDiffusionGradientDrift () const noexcept |
| Check if the grad(D) drift correction is enabled. | |
| virtual void | updateDiffusion () |
| Update mobilities parametrically from the particle energy. | |
| virtual void | organizeParticlesByCell (WhichContainer a_container) |
| Sort the input particle container by cell. | |
| virtual void | organizeParticlesByPatch (WhichContainer a_container) |
| Sort the input particle container by patch. | |
| virtual void | makeSuperparticles (WhichContainer a_container) |
| Make superparticles for a full container, merging to the solver's configured target. | |
| virtual void | makeSuperparticles (WhichContainer a_container, int a_particlesPerCell) |
| Make superparticles for a full container – this is the AMR version that users will usually call. | |
| virtual void | makeSuperparticles (WhichContainer a_container, const Vector< int > &a_particlesPerCell) |
| Make superparticles for a full container – this is the AMR version that users will usually call. | |
| virtual void | makeSuperparticles (WhichContainer a_container, const Vector< int > &a_particlesPerCell, const ParticleManagement::ParticleMergeMethod a_method) |
| Make superparticles with an explicitly chosen method, ignoring the configured merge_method. | |
| virtual const Vector< int > & | getParticlesPerCell () const noexcept |
| Get the configured target number of computational particles per cell, per AMR level. | |
| virtual ParticleContainer< ItoMergeParticle > & | getRegridParticles () noexcept |
| Get the reduced holder the bulk particles ride across a regrid in. | |
| virtual void | remap () |
| Remap the bulk particle container. | |
| virtual void | remap (WhichContainer a_container) |
| Remap all particles in the input container. | |
| virtual void | remapAll () |
| Remap all particle containers. | |
| RealVect | randomGaussian () const |
| Draw a random N-dimensional Gaussian number from a normal distribution with zero with and unit standard deviation. | |
| RealVect | randomDirection () const |
| Draw a random direction in N-dimensional space. | |
| virtual Real | computeDt () const |
| Compute a time step for the advance – this calls the level function. | |
| virtual Real | computeDt (int a_lvl) const |
| Compute a time step for the advance – this returns the maximum permitted time step on the input grid level. | |
| virtual Real | computeDt (int a_lvl, const DataIndex &a_dit) const |
| Compute a time step for the advance – this returns the maximum permitted time step on the input grid patch. | |
| virtual Real | computeHopDt (Real a_maxCellsToMove) const |
| Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on any grid level. | |
| virtual Real | computeHopDt (Real a_maxCellsToMove, int a_lvl) const |
| Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on the input grid level. | |
| virtual Real | computeHopDt (Real a_maxCellsToMove, int a_lvl, const DataIndex &a_dit) const |
| Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on the input grid level. | |
| virtual Real | computeAdvectiveDt () const |
| Compute advection time step dt = dx/vMax where vMax is the largest velocity component of the particle. | |
| virtual Real | computeAdvectiveDt (int a_lvl) const |
| Compute the drift dt. This computes the minimum dt = dx/vMax on the input level. | |
| virtual Real | computeAdvectiveDt (int a_lvl, const DataIndex &a_dit) const |
| Compute the drift dt. This computes the minimum dt = dx/vMax on one level and one box. | |
| virtual Real | computeDiffusiveDt () const |
| Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles. | |
| virtual Real | computeDiffusiveDt (int a_lvl) const |
| Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles on the input level. | |
| virtual Real | computeDiffusiveDt (int a_lvl, const DataIndex &a_dit) const |
| Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles on the input grid patch. | |
| DepositionType | getDeposition () const |
| Get deposition method. | |
| CoarseFineDeposition | getCoarseFineDeposition () const |
| Get the coarse-fine deposition strategy. | |
| phase::which_phase | getPhase () const |
| Return phase. | |
Protected Types | |
| enum class | WhichCheckpoint { Particles , Numbers } |
| How to checkpoint files. More... | |
| enum class | WhichMobilityInterpolation { Direct , Velocity } |
| Enum for deciding how to interpolate particle mobilities. More... | |
Protected Member Functions | |
| void | parseRNG () |
| Parse RNG options – this parses the RNG seed and instantiates the distributions. | |
| void | parseTruncation () |
| Parse the normal distribution truncation level. | |
| void | parseDeposition () |
| Parse particle deposition methods. | |
| void | parseParticleMerger () |
| Parse the super-particle merger. | |
| void | mergeLite (ParticleContainer< ItoMergeParticle > &a_particles, const Vector< int > &a_particlesPerCell, ParticleManagement::ParticleMergeMethod a_method) |
| Run one merge method over an already-extracted reduced-particle container. | |
| void | applyCellMerger (ParticleContainer< ItoMergeParticle > &a_particles, const Vector< int > &a_particlesPerCell, const ParticleManagement::ParticleMerger< ItoMergeParticle > &a_merger) |
| Apply a per-cell merger over an entire reduced-particle container, cell by cell. | |
| void | invalidateParticleIDs (ParticleContainer< ItoMergeParticle > &a_particles) const |
| Set every particle id in a reduced-particle container to ParticleSoA::s_invalidID. | |
| void | extractIntoMergeContainer (WhichContainer a_container, ParticleContainer< ItoMergeParticle > &a_merge) |
| Extract a container's ItoParticles into a minimal ItoMergeParticle container on the same realm/patch, then clear the ItoParticles. | |
| void | splitFromMergeContainer (ParticleContainer< ItoMergeParticle > &a_merge, int a_numParticlesPerCellThresh) |
| Split every under-full cell up to the target count. | |
| void | rebuildFromMergeContainer (WhichContainer a_container, ParticleContainer< ItoMergeParticle > &a_merge) |
| Rebuild a container's ItoParticles from the reduced particles. | |
| Real | kdWeightMedianCellWidths () const noexcept |
| Turn ItoSolver.kd_partition (and, for 'hybrid', ItoSolver.kd_hybrid_leaf_dx) into the single crossover length every kd tree build takes. | |
| void | mergeKDCell (ParticleContainer< ItoMergeParticle > &a_particles, const Vector< int > &a_particlesPerCell) |
| Cell-based merge: partition each cell's particles with a kd tree and reduce every leaf to one particle. | |
| void | mergeReinitialize (ParticleContainer< ItoMergeParticle > &a_particles, const Vector< int > &a_particlesPerCell) |
| Cell-based merge: redistribute each cell's physical particles into near-equal integer weights at random cell positions. | |
| template<ParticleManagement::NNSearch Backend> | |
| void | mergeNnPairSearch (ParticleContainer< ItoMergeParticle > &merge, const Vector< int > &a_particlesPerCell) |
| Whole-container merge: distributed nearest-neighbour pair merge – shared implementation behind nn_search = tree and nn_search = hash. | |
| void | mergeNnPairOneCell (ParticleContainer< ItoMergeParticle > &merge, const Vector< int > &a_particlesPerCell) |
| Whole-container merge: distributed nearest-neighbour pair merge, per-cell PointCloudBVH search. | |
| void | mergeKDSkinNn (ParticleContainer< ItoMergeParticle > &merge, const Vector< int > &a_particlesPerCell) |
| Whole-container merge: kd-tree with a nearest-neighbour skin (kd_amr_boundary = nn). | |
| void | mergeKDImpl (ParticleContainer< ItoMergeParticle > &merge, const Vector< int > &a_particlesPerCell, bool a_enableBoundaryCarve) |
| Whole-container merge: whole-patch kd-tree build – shared implementation behind kd_patch and kd_amr with kd_amr_boundary = carve. | |
| void | parseIntersectionEB () |
| Parse EB intersection algorithms. | |
| void | parseVerbosity () |
| Parse class verbosity. | |
| void | parsePlotVariables () |
| Parse plot variables. | |
| void | parseDiffusionHop () |
| Parse diffusion hop. | |
| void | parseDiffusionGradient () |
| Parse whether or not to add the grad(D) drift correction. | |
| void | parseCheckpointing () |
| Parse checkpointing method. | |
| void | drawNewParticles (const LevelData< EBCellFAB > &a_particlesPerCell, int a_level, int a_newPPC) |
| Restart particles from a specified number of particles in the grid cell. | |
| virtual void | redistributeAMR (EBAMRCellData &a_phi) const |
| Redistribute mass in an AMR context. | |
| virtual void | depositNonConservative (EBAMRIVData &a_depositionNC, const EBAMRCellData &a_depositionKappaC) const |
| Make the "non-conservative" kappa deposition – computing depositionNC = sum(kappa*depositionC)/sum(kappa) in a neighborhood around each vof. | |
| virtual void | depositHybrid (EBAMRCellData &a_depositionH, EBAMRIVData &a_massDifference, const EBAMRIVData &a_depositionNC) const |
| Make the "hybrid" deposition phiH = kappa*phiC + (1-kappa)*phiNC. On input, a_depositionH should contain phiC. | |
| virtual void | interpolateMobilitiesDirect (int a_lvl, const DataIndex &a_dit) noexcept |
| Directly interpolate mobilities. Interpolates for all particles in the specified grid patch. | |
| virtual void | interpolateMobilitiesVelocity (int a_lvl, const DataIndex &a_dit, const EBCellFAB &a_velocityMagnitude) noexcept |
| Interpolate mobilities through the velocity. Interpolates for all particles in the specified grid patch. | |
| virtual void | updateMobilities (int a_level, const DataIndex &a_dit) |
| Update mobilities parametrically from the particle energy. | |
| virtual void | interpolateDiffusion (int a_lvl, const DataIndex &a_dit) |
| Interpolate the diffusion field to the particle positions. | |
| virtual void | updateDiffusion (int a_level, const DataIndex &a_dit) |
| Update mobilities parametrically from the particle energy. | |
| virtual void | writeData (LevelData< EBCellFAB > &a_output, int &a_comp, const EBAMRCellData &a_data, const std::string &a_outputRealm, int a_level, bool a_interpToCentroids, bool a_interpGhost) const noexcept |
| Write data to output. Convenience function. | |
Protected Attributes | |
| WhichCheckpoint | m_checkpointing |
| How to checkpoint files. particles => write particles to HDF5. numbers => write numbers to HDF5. | |
| WhichMobilityInterpolation | m_mobilityInterp |
| Switch for deciding how to interpolate mobilities, i.e. interpolating either mu*E or just mu (to the particle position) | |
| ParticleManagement::ParticleMerger< ItoMergeParticle > | m_particleCellMerger |
| User-supplied per-cell merger for merge_method = external (set via setParticleCellMerger()). The built-in methods build their own merger locally in the corresponding mergeXxx(). | |
| ParticleManagement::ParticleMergeMethod | m_mergeMethod = ParticleManagement::ParticleMergeMethod::KdCell |
| The configured merge method (which scope the merge groups particles over). | |
| ParticleManagement::KDPartition | m_kdPartition = ParticleManagement::KDPartition::Weight |
| kd_cell/kd_patch/kd_amr: how each node is divided into two children. | |
| ParticleManagement::KDPlacement | m_kdPlacement = ParticleManagement::KDPlacement::Centroid |
| kd_cell/kd_patch/kd_amr: where the particle a leaf reduces to is placed. | |
| ParticleManagement::KDSplitPlacement | m_kdSplitPlacement = ParticleManagement::KDSplitPlacement::Center |
| Where the pieces of a split particle are placed. | |
| ParticleManagement::KDAmrBoundary | m_kdAmrBoundary = ParticleManagement::KDAmrBoundary::Carve |
| kd_amr: how leaves that touch a patch or rank boundary are resolved. | |
| ParticleManagement::NNSearch | m_nnSearch = ParticleManagement::NNSearch::Tree |
| nn_amr: which spatial index the neighbour search is backed by. | |
| Vector< int > | m_particlesPerCell |
| Target number of computational particles per cell, per AMR level. | |
| std::optional< ParticleManagement::ParticleMergeMethod > | m_regridMergeMethod |
| Which merge method to run inside ItoSolver::regrid(), or nullopt for "whatever
merge_method says". | |
| bool | m_nnIterate = true |
| nn_amr: iterate the local trivial tier to convergence within each round. | |
| int | m_nnFallback = 1 |
| nn_amr: number of fallback candidates per query. The k-nearest search is done with k = 1 + this. Also read by kd_amr with kd_amr_boundary = nn. | |
| int | m_nnMaxCellDistance = -1 |
| nn_amr: maximum merge distance in whole cells (Chebyshev). A negative value means unbounded (std::nullopt). Not read when nn_search = onecell, whose merge distance is structurally fixed at 1. | |
| int | m_nnMaxRounds = 3 |
| nn_amr: maximum number of drain rounds run per makeSuperparticles() call. | |
| Real | m_kdHybridLeafDx = 1.0 |
| kd_partition = hybrid: node size, in cell widths, at or below which the split plane switches from the count median to the weight median. | |
| int | m_restartPPC |
| Number of particles used when restarting a simulation – this is relevant only when restarting from a "fluid" checkpoint file. | |
| std::string | m_realm |
| Realm where this solve lives. | |
| RefCountedPtr< ComputationalGeometry > | m_computationalGeometry |
| Computational geometry. | |
| RefCountedPtr< AmrMesh > | m_amr |
| AMR; needed for grid stuff. | |
| RefCountedPtr< ItoSpecies > | m_species |
| Species that this solver solves for. | |
| phase::which_phase | m_phase |
| Phase where this solver lives. | |
| std::string | m_name |
| Solver name. | |
| std::string | m_className |
| Class name. | |
| Real | m_normalDistributionTruncation |
| Truncation value for normal distribution. | |
| Real | m_bisectionStep |
| Bisection step size to use for particle intersection tests with EBs. | |
| int | m_verbosity |
| Verbosity level for this solver. | |
| int | m_timeStep |
| Time step. | |
| Real | m_time |
| Current time. | |
| Real | m_dt |
| Time step. | |
| IrregularDeposition | m_irregularDeposition |
| How the cut cells are treated when depositing. | |
| bool | m_forceIrregInterpolationNGP |
| NGP interpolation in cut cells or not. | |
| bool | m_forceHaloNGP |
| Force usage of NGP when depositing "halo" particles. | |
| bool | m_isDiffusive |
| If true, solver is diffusive. | |
| bool | m_isMobile |
| If true, solver is mobile, i.e. advection is turned on. | |
| bool | m_diffusionGradientDrift |
| If true, grad(D) is added to the particle drift. | |
| bool | m_plotPhi |
| Flag for outputting m_phi to plot files. | |
| bool | m_plotVelocity |
| Flag for outputting m_velocityFunction to plot files. | |
| bool | m_plotDiffCo |
| Flag for outputting m_diffusionFunction to plot files. | |
| bool | m_plotDiffusionGradient |
| Flag for outputting m_diffusionGradient to plot files. | |
| bool | m_plotParticles |
| Flag for depositing and plotting the bulk particles on the mesh. | |
| bool | m_plotParticlesEB |
| Flag for depositing and plotting the EB particles on the mesh. | |
| bool | m_plotParticlesDomain |
| Flag for depositing and plotting the domain particles on the mesh. | |
| bool | m_plotParticlesSource |
| Flag for depositing and plotting the source particles on the mesh. | |
| bool | m_plotParticlesCovered |
| Flag for depositing and plotting the covered particles on the mesh. | |
| bool | m_plotEnergyDensity |
| Flag for plotting the energy density on the mesh. | |
| bool | m_plotAverageEnergy |
| Flag for plotting the average particle energy on the mesh. | |
| DepositionType | m_deposition |
| Deposition method when depositing particles to the mesh. | |
| CoarseFineDeposition | m_coarseFineDeposition |
| Coarse-fine deposition strategy. | |
| DepositionType | m_plotDeposition |
| Deposition method when depositing particles to mesh during plotting. | |
| EBAMRCellData | m_phi |
| Storage for particle mesh data. | |
| EBAMRCellData | m_mobilityFunction |
| Mobility function – used when interpolating particle mobilities. | |
| EBAMRCellData | m_velocityFunction |
| Cell-centered field used for interpolating velocities. | |
| EBAMRCellData | m_diffusionFunction |
| Diffusion-centerer field used for interpolating diffusion coefficients. | |
| EBAMRCellData | m_diffusionGradient |
| Cell-centered gradient of m_diffusionFunction, used for the grad(D) drift correction. | |
| EBAMRFAB | m_kdMergeCellHistogram |
| Per-cell occupancy scratch for the kd merges (see ParticleManagement::mergeKDCarve). | |
| EBAMRFAB | m_kdMergeLeafQuota |
| Per-cell merge-quota scratch for the kd merges. Same lifetime as m_kdMergeCellHistogram. | |
| EBAMRIVData | m_depositionNC |
| Scratch storage for holding the non-conservative deposition. | |
| EBAMRIVData | m_massDiff |
| Scratch storage for holding the mass difference when using hybrid deposition. | |
| ParticleContainer< NoPayload > | m_mirrorImages |
| Reflected images of the band particles, for IrregularDeposition::Mirror. | |
| EBAMRCellData | m_mirrorScratch |
| Mesh scratch the mirror images deposit into, before being added to the real field. | |
| std::map< WhichContainer, ParticleContainer< ItoParticle > > | m_particleContainers |
| Various particle containers with identifiers. | |
| ParticleContainer< ItoMergeParticle > | m_regridParticles |
| The bulk particles, in reduced form, between preRegrid() and regrid(). | |
| EBIntersection | m_intersectionAlg |
| Algorithm for EB intersection. | |
Detailed Description
Base class for Ito diffusion particle models.
This is a particle class for solving Ito diffusion problems dX = v*dt + sqrt(2*D)*dW_t (dW_t is a Wiener process over dt) over an AMR hierarchy. The diffusion coefficient is related to the hydrodynamic diffusion coefficient by D(fluid) = sqrt(2*D(Ito)).
- Note
- To use this class, the user must add a species and set the realm and phase where the solver will live.
Member Enumeration Documentation
◆ WhichCheckpoint
|
strongprotected |
How to checkpoint files.
Particles => Write particles to HDF5. Numbers => Write particle numbers to HDF5 (and lose information)
◆ WhichContainer
|
strong |
Enum class for distinguishing various types of particle containers.
This exists because the ItoSolver can partition particles into various containers, which is very useful when one wants to add particles from a source term, remove particles that fall inside the EB, or parse boundary conditions on the EB and domain faces. Here, Bulk = "Active" particles, EB = Particles on the EBs , Domain = Particles on the domain sides, Source = Source particles – used to e.g. add new particles to the bulk particles, Covered = Particles inside the EB, Scratch = Scratch particles
◆ WhichMobilityInterpolation
|
strongprotected |
Enum for deciding how to interpolate particle mobilities.
Direct => Interpolate particle mobilities from the mesh. Velocity => Set particle mobilitys by computing mu = |v|/|V| where v is the particle velocity and V is the "velocity field".
Member Function Documentation
◆ allocate()
|
virtual |
Allocate internal storage.
This will allocate the required mesh data as well as all the particle data holders.
- Note
- Storage for diffusion and advection fields are only allocate if the species is diffusive/mobile.
◆ applyCellMerger()
|
protected |
Apply a per-cell merger over an entire reduced-particle container, cell by cell.
Shared machinery for every cell-based merge: the container is cell-sorted here (organizeParticlesByCell()); for each non-empty cell the particles are extracted, passed to a_merger with the cell's CellInfo and target count, and the result rebuilt into the leaf.
- Parameters
-
[in,out] a_particles Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count per cell (per-level; the last entry applies to any finer level). [in] a_merger The per-cell merger to apply.
◆ clear() [1/2]
|
virtual |
Clear a particle container – this will delete all the particles in the input container.
- Parameters
-
[in] a_particles Particle container to be emptied.
◆ clear() [2/2]
|
virtual |
Clear a particle container – this will delete all the particles in the input container.
- Parameters
-
[in] a_container Container
◆ coarsenAndFillGhosts()
| void ItoSolver::coarsenAndFillGhosts | ( | EBAMRCellData & | a_phi | ) | const |
Coarsen the input data and interpolate its ghost cells.
This is the AMR synchronization that a deposit does not do for itself. Whether it is wanted depends on what the caller does next: a deposit that is the final state of a field needs it, whereas a deposit that is one term in a sum does not – there, only the assembled sum needs synchronizing, and doing it per term produces values that are immediately overwritten. Deposits therefore leave it to the caller.
- Parameters
-
[in,out] a_phi Cell-centered mesh data (one component).
◆ computeAdvectiveDt() [1/3]
|
virtual |
Compute advection time step dt = dx/vMax where vMax is the largest velocity component of the particle.
- Returns
- Computed advective dt
- Note
- The grad(D) drift correction (ItoSolver.diffusion_grad_drift) is not accounted for here. These estimates are built from the particle velocity and diffusion columns, and grad(D) lives on neither – it is interpolated at the point of use and added to the displacement by the time stepper. The omission is deliberate rather than an oversight: the correction displaces a particle by dt*grad(D), which for a streamer in atmospheric air (D ~ 0.1 m^2/s varying over ~10 um, so |grad D| ~ 1e4 m/s) is about two percent of the diffusion hop sqrt(2*D*dt) at dt = 1 ps, and the hop is what the diffusive limit already bounds. A model that made grad(D) comparable to the drift velocity would make these estimates optimistic.
◆ computeAdvectiveDt() [2/3]
|
virtual |
Compute the drift dt. This computes the minimum dt = dx/vMax on the input level.
- Parameters
-
[in] a_lvl Grid level
- Returns
- Computed advective dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeAdvectiveDt() [3/3]
|
virtual |
Compute the drift dt. This computes the minimum dt = dx/vMax on one level and one box.
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
- Returns
- Computed advective dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeAverageDiffusion()
|
virtual |
Compute average diffusion coefficient.
This computes the average diffusion coefficient as D_avg = sum(mass*D)/sum(mass) by depositing on the mesh.
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
◆ computeAverageEnergy()
|
virtual |
Compute average particle energy..
This computes the average energy as E_avg = sum(mass*energy)/sum(mass) by depositing on the mesh.
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
◆ computeAverageMobility()
|
virtual |
Compute average mobility.
This computes the average mobility as mu_avg = sum(mass*mu)/sum(mass) by depositing on the mesh.
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
◆ computeDiffusionGradient()
|
virtual |
Compute the cell-centered gradient of the mesh diffusion field.
Fills m_diffusionGradient with grad(Df), where Df is the mesh diffusion field, and then coarsens the result and updates its ghost cells. The caller must have brought m_diffusionFunction's own ghost cells up to date first – the gradient stencil reaches into them and across refinement boundaries. Does nothing when the solver is not diffusive or when ItoSolver.diffusion_grad_drift is false, in which case m_diffusionGradient is not allocated.
◆ computeDiffusiveDt() [1/3]
|
virtual |
Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles.
- Returns
- Computed diffusive dt
- Note
- The grad(D) drift correction (ItoSolver.diffusion_grad_drift) is not accounted for here. These estimates are built from the particle velocity and diffusion columns, and grad(D) lives on neither – it is interpolated at the point of use and added to the displacement by the time stepper. The omission is deliberate rather than an oversight: the correction displaces a particle by dt*grad(D), which for a streamer in atmospheric air (D ~ 0.1 m^2/s varying over ~10 um, so |grad D| ~ 1e4 m/s) is about two percent of the diffusion hop sqrt(2*D*dt) at dt = 1 ps, and the hop is what the diffusive limit already bounds. A model that made grad(D) comparable to the drift velocity would make these estimates optimistic.
◆ computeDiffusiveDt() [2/3]
|
virtual |
Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles on the input level.
- Parameters
-
[in] a_lvl Grid level
- Returns
- Computed diffusive dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeDiffusiveDt() [3/3]
|
virtual |
Compute the diffusive dt. This computes dt = dx*dx/(2*SpaceDim*D) for all particles on the input grid patch.
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
- Returns
- Computed diffusive dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeDt() [1/3]
|
virtual |
Compute a time step for the advance – this calls the level function.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not have a fundamental time step limitation, so these limits "replicate" the time step selections in a 1D fluid model. If we only use advection advection the time step is computed as dt = dx/sum(|V_i|) = dtA. If only diffusion is active the time step is computed as dt = (dx*dx)/(2*SpaceDim*D) = dtD. If both advection and diffusion are active the time step is computed as dt = 1/(1/dtA + 1/dtD).
- Returns
- Computed dt
- Note
- The grad(D) drift correction (ItoSolver.diffusion_grad_drift) is not accounted for here. These estimates are built from the particle velocity and diffusion columns, and grad(D) lives on neither – it is interpolated at the point of use and added to the displacement by the time stepper. The omission is deliberate rather than an oversight: the correction displaces a particle by dt*grad(D), which for a streamer in atmospheric air (D ~ 0.1 m^2/s varying over ~10 um, so |grad D| ~ 1e4 m/s) is about two percent of the diffusion hop sqrt(2*D*dt) at dt = 1 ps, and the hop is what the diffusive limit already bounds. A model that made grad(D) comparable to the drift velocity would make these estimates optimistic.
◆ computeDt() [2/3]
|
virtual |
Compute a time step for the advance – this returns the maximum permitted time step on the input grid level.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not have a fundamental time step limitation, so these limits "replicate" the time step selections in a 1D fluid model. If we only use advection advection the time step is computed as dt = dx/Vmax = dtA, where Vmax is the largest velocity component along any of the directions. If only diffusion is active the time step is computed as dt = (dx*dx)/(2*SpaceDim*D) = dtD. If both advection and diffusion are active the time step is computed as dt = 1/(1/dtA + 1/dtD).
- Parameters
-
[in] a_lvl Grid level
- Returns
- Computed dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeDt() [3/3]
|
virtual |
Compute a time step for the advance – this returns the maximum permitted time step on the input grid patch.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not have a fundamental time step limitation, so these limits "replicate" the time step selections in a 1D fluid model. If we only use advection advection the time step is computed as dt = dx/Vmax = dtA, where Vmax is the largest velocity component along any of the directions. If only diffusion is active the time step is computed as dt = (dx*dx)/(2*SpaceDim*D) = dtD. If both advection and diffusion are active the time step is computed as dt = 1/(1/dtA + 1/dtD).
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
- Returns
- Computed dt
- Note
- Does not account for the grad(D) drift correction – see computeDt().
◆ computeHopDt() [1/3]
|
virtual |
Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on any grid level.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not a fundamental time step limitation, so this function does its best at computing a time step such that the particles do not move more than the specified amount of grid cells. If only advection is active the time step is computed as dt = a_maxCellsToMove * dx/vMax where vMax is the largest velocity component. If only diffusion is active the usual kernel is dX = dWt which yields a "hop" of length L_d = sqrt(2*D*dt)*N0 where N0 is the diffusion hop in one of the coordinates. We do not need to worry about SpaceDim-related corrections because the hops in each direction are independent, so solving for dt we find dtD = L_d^2/(2*D*N0^2). If both advectino and diffusion are active then we can move up to L_d = v_d*dt + sqrt(2*D*dt)*N0 in any one coordinate direction (this is the usual Ito kernel). This requires a solution to a quadratic equation. Fortunately, this is easy to solve for.
- Parameters
-
[in] a_maxCellsToMove
- Returns
- Computed hop dt
◆ computeHopDt() [2/3]
|
virtual |
Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on the input grid level.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not a fundamental time step limitation, so this function does its best at computing a time step such that the particles do not move more than the specified amount of grid cells. If only advection is active the time step is computed as dt = a_maxCellsToMove * dx/vMax where vMax is the largest velocity component. If only diffusion is active the usual kernel is dX = dWt which yields a "hop" of length L_d = sqrt(2*D*dt)*N0 where N0 is the diffusion hop in one of the coordinates. We do not need to worry about SpaceDim-related corrections because the hops in each direction are independent, so solving for dt we find dtD = L_d^2/(2*D*N0^2). If both advectino and diffusion are active then we can move up to L_d = v_d*dt + sqrt(2*D*dt)*N0 in any one coordinate direction (this is the usual Ito kernel). This requires a solution to a quadratic equation. Fortunately, this is easy to solve for.
- Parameters
-
[in] a_maxCellsToMove Maximum number of cells to move with a standard Ito kernel dX = v*dt + sqrt(2*D*dt)*N [in] a_lvl Grid level
- Returns
- Computed hop dt
◆ computeHopDt() [3/3]
|
virtual |
Compute the largest possible time step such that the particles does not move more than a specified number of grid cells on the input grid level.
This computes the time step differently whether or not diffusion and advection are active. The Ito particle model does not a fundamental time step limitation, so this function does its best at computing a time step such that the particles do not move more than the specified amount of grid cells. If only advection is active the time step is computed as dt = a_maxCellsToMove * dx/vMax where vMax is the largest velocity component. If only diffusion is active the usual kernel is dX = dWt which yields a "hop" of length L_d = sqrt(2*D*dt)*N0 where N0 is the diffusion hop in one of the coordinates. We do not need to worry about SpaceDim-related corrections because the hops in each direction are independent, so solving for dt we find dtD = L_d^2/(2*D*N0^2). If both advectino and diffusion are active then we can move up to L_d = v_d*dt + sqrt(2*D*dt)*N0 in any one coordinate direction (this is the usual Ito kernel). This requires a solution to a quadratic equation. Fortunately, this is easy to solve for.
- Parameters
-
[in] a_maxCellsToMove Maximum number of cells to move with a standard Ito kernel dX = v*dt + sqrt(2*D*dt)*N [in] a_lvl Grid level [in] a_dit Grid index
- Returns
- Computed hop dt
◆ computeLoads()
|
virtual |
Compute particle load on a specific grid level – this will compute the number of particles in each box in the input grids.
- Parameters
-
[out] a_loads Loads on each grid patch. This follows the order from a_dbl.boxArray() [in] a_dbl Grids [in] a_level Grid level
◆ depositConductivity() [1/2]
|
virtual |
Deposit conductivities (i.e. mass*mobility / volume)
This deposits mass*mobility (not multiplied by charge)
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
◆ depositConductivity() [2/2]
|
virtual |
Deposit conductivities (i.e. mass*mobility / volume)
This deposits mass*mobility (not multiplied by charge)
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data [in] a_deposition Deposition method [in] a_coarseFineDeposition Coarse-fine deposition method.
◆ depositDiffusivity() [1/2]
|
virtual |
Deposit diffusivity (i.e. mass*D/volume)
This deposits mass*diffusion (not multiplied by charge)
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
- Note
- Calls the other versions with a_deposition = m_deposition
◆ depositDiffusivity() [2/2]
|
virtual |
Deposit diffusivity (i.e. mass*D/volume)
This deposits mass*mobility (not multiplied by charge)
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data [in] a_deposition Deposition method [in] a_coarseFineDeposition Coarse-fine deposition method.
◆ depositEnergyDensity() [1/2]
|
virtual |
Deposit energy densities (i.e. mass*energy/volume => total energy per unit volume)
This deposits mass*energy
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data
- Note
- Calls the other versions with a_deposition = m_deposition
◆ depositEnergyDensity() [2/2]
|
virtual |
Deposit energy densities (i.e. mass*energy/volume => total energy per unit volume)
This deposits mass*energy
- Parameters
-
[out] a_phi Mesh data [in] a_particles Particle data [in] a_deposition Deposition method [in] a_coarseFineDeposition Coarse-fine deposition method.
◆ depositGathered()
| void ItoSolver::depositGathered | ( | EBAMRCellData & | a_phi, |
| const ParticleContainer< ItoParticle > & | a_particles, | ||
| DepositionType | a_deposition, | ||
| CoarseFineDeposition | a_coarseFineDeposition, | ||
| Gather | a_gather | ||
| ) | const |
Deposit a gathered per-particle quantity on the mesh (kappa-conservative + redistribution).
- Parameters
-
[out] a_phi Mesh data – must have exactly one component. [in] a_particles SoA particles to be deposited. [in] a_deposition Deposition method. [in] a_coarseFineDeposition Coarse-fine deposition strategy. [in] a_gather Per-particle value gatherer (leaf, index) -> Real.
- Template Parameters
-
Gather Callable (const ParticleSoA<ItoParticle>&, std::size_t) -> Real.
- Note
- This leaves coarse levels un-averaged and ghost cells stale. Call coarsenAndFillGhosts() afterwards unless the result is a term in a sum that the caller synchronizes itself.
◆ depositGatheredNGP()
|
noexcept |
Do an NGP deposit of a gathered per-particle quantity on a specific grid level. Used for IO.
- Parameters
-
[out] a_output Contains NGP deposition of the gathered quantity. Ignores cut-cells. [in] a_particles SoA particles. [in] a_level Grid level. [in] a_gather Per-particle value gatherer (leaf, index) -> Real.
- Template Parameters
-
Gather Callable (const ParticleSoA<ItoParticle>&, std::size_t) -> Real.
◆ depositHybrid()
|
protectedvirtual |
Make the "hybrid" deposition phiH = kappa*phiC + (1-kappa)*phiNC. On input, a_depositionH should contain phiC.
- Parameters
-
[in,out] a_depositionH On input, contains phiC. On output, contain phiH [out] a_massDifference On output, contains mass loss in each cut-cell. [in] a_depositionNC The "non-conservative" deposited variable.
◆ depositNonConservative()
|
protectedvirtual |
Make the "non-conservative" kappa deposition – computing depositionNC = sum(kappa*depositionC)/sum(kappa) in a neighborhood around each vof.
- Parameters
-
[out] a_depositionNC Non-conservative deposition [in] a_depositionKappaC Conserved deposition
◆ depositParticles() [1/2]
|
virtual |
Deposit particles onto mesh.
This will deposit the mass (i.e., computational weight) "bulk" particles into m_phi.
- Note
- Calls the other version with a_container = WhichContainer::Bulk
◆ depositParticles() [2/2]
|
virtual |
Deposit particles on to mesh.
- Parameters
-
[in] a_container Which container to deposit.
This will deposit mass (i.e., computational weight) of the the input particle container particles onto the classes member 'm_phi'.
- Note
- Calls the general version with arguments: m_phi, m_particles.at(a_container), m_deposition.
◆ depositWeight()
| void ItoSolver::depositWeight | ( | EBAMRCellData & | a_phi, |
| const ParticleContainer< P, Traits > & | a_particles, | ||
| DepositionType | a_deposition, | ||
| CoarseFineDeposition | a_coarseFineDeposition | ||
| ) | const |
Deposit the SoA weight column on the mesh (kappa-conservative + redistribution).
The container payload is a template parameter so that auxiliary point-particle containers – e.g. the rho-dagger and conductivity particles carried by the semi-implicit time steppers – deposit through exactly the same pipeline as the solver's own particles. This includes the cut-cell deposition flag and the redistribution, both of which must be identical if the deposited densities are to be in the same normalization.
- Note
- This leaves coarse levels un-averaged and ghost cells stale. Call coarsenAndFillGhosts() afterwards unless the result is a term in a sum that the caller synchronizes itself.
- Parameters
-
[out] a_phi Mesh data – must have exactly one component. [in] a_particles SoA particles to be deposited. [in] a_deposition Deposition method. [in] a_coarseFineDeposition Coarse-fine deposition strategy.
- Template Parameters
-
P Payload type of the container. Traits Column descriptor for the payload.
◆ depositWeightNGP()
|
noexcept |
Do an NGP deposit of the SoA weight column on a specific grid level. Used for IO.
- Parameters
-
[out] a_output Contains NGP deposition of particle weights. Ignores cut-cells. [in] a_particles SoA particles. [in] a_level Grid level.
◆ drawNewParticles()
|
protected |
Restart particles from a specified number of particles in the grid cell.
This will instantiate the bulk particles by randomly drawing new particles in each grid cell.
- Parameters
-
[in] a_particlesPerCell Mesh data showing how many particles are in each cell. [in] a_level Grid level. [in] a_newPPC Desired number of computational particles per cell
◆ extractIntoMergeContainer()
|
protected |
Extract a container's ItoParticles into a minimal ItoMergeParticle container on the same realm/patch, then clear the ItoParticles.
Copies position + weight + particleID + energy only; velocity/mobility/diffusion are dropped (they are recomputed from the field after the merge). No remap is needed since positions/ownership are unchanged. Ghost particles are cleared first – the copy loop has no isGhost() test and would promote a ghost to an owned particle. Each source leaf's arena is released as soon as its reduced copy exists, so the two representations overlap by one patch rather than one level.
- Parameters
-
[in] a_container Which container to extract from. [out] a_merge The resulting minimal-payload container, allocated on m_realm.
◆ generateParticlesFromDensity() [1/2]
|
virtualnoexcept |
Fill a particle container randomly with particles such that we obtain the target uniform density, with a per-level cap on the computational particle count.
The per-level form of the overload below. Used by initialData(), which seeds at ItoSolver.particles_per_cell – a per-level vector – so that a cold start and the first merge agree on the target by construction instead of seeding high and immediately merging back down.
- Parameters
-
[in,out] a_particles Particle container to fill. Particles already in the container will be kept. [in] a_densityFunc Density function. [in] a_maxParticlesPerCell Maximum computational particles generated per cell, per level; the last entry applies to any finer level.
◆ generateParticlesFromDensity() [2/2]
|
virtualnoexcept |
Fill a particle container randomly with particles such that we obtain the target uniform density.
- Parameters
-
[in,out] a_particles Particle container to fill. Particles already in the container will be kept. [in] a_densityFunc Density function. [in] a_maxParticlesPerCell Maximum number of computational particles generated per cell.
◆ getBisectionStep()
|
virtualnoexcept |
Get the path-march length used by the bisection intersection algorithm.
Only meaningful when the intersection algorithm is EBIntersection::Bisection, which marches the particle path in intervals of this length and refines the first interval that brackets the surface.
- Returns
- Bisection step length.
◆ getCoarseFineDeposition()
| CoarseFineDeposition ItoSolver::getCoarseFineDeposition | ( | ) | const |
Get the coarse-fine deposition strategy.
- Returns
- Coarse fine deposition
◆ getDeposition()
| DepositionType ItoSolver::getDeposition | ( | ) | const |
Get deposition method.
- Returns
- Returns m_deposition
◆ getDiffusionFunction() [1/2]
|
virtual |
Get the diffusion function.
- Returns
- m_diffusionFunction
◆ getDiffusionFunction() [2/2]
|
virtual |
Get the diffusion function.
- Returns
- m_diffusionFunction
◆ getIntersectionAlgorithm()
|
virtualnoexcept |
Get the EB-particle intersection algorithm.
- Returns
- Intersection algorithm
◆ getMobilityFunction() [1/2]
|
virtual |
Get mobility function.
- Returns
- m_mobilityFunction
◆ getMobilityFunction() [2/2]
|
virtual |
Get mobility function.
- Returns
- m_mobilityFunction
◆ getName()
|
virtual |
Get this solver's name.
- Returns
- Returns m_name
◆ getNumberOfPlotVariables()
|
virtual |
Get number of plot variables.
- Returns
- Returns the number of plot variables (Note: Scalars-> one variable and vectors -> SpaceDim variables).
◆ getNumParticles()
|
virtual |
Get number of particles in a specified particle container.
- Parameters
-
[in] a_whichContainer Container [in] a_localOnly Only report local particles (i.e. not reduced over MPI ranks)
- Returns
- Num particles
◆ getParticles() [1/2]
|
virtual |
Get a general particle container.
- Parameters
-
[in] a_container Which container to fetch.
- Returns
- Particles
◆ getParticles() [2/2]
|
virtual |
Get a general particle container.
- Parameters
-
[in] a_container Which container to fetch.
- Returns
- Particles
◆ getParticlesPerCell()
|
virtualnoexcept |
Get the configured target number of computational particles per cell, per AMR level.
ItoSolver.particles_per_cell. Exposed because a load estimator has to assume the same target the merge will actually reduce to – BrownianWalkerStepper's mesh balancer clamps its per-cell physical count with it. Index it with the same clamp the merge uses: entry lvl if the vector is long enough, otherwise the last entry.
- Returns
- The per-level target particle count.
◆ getPhase()
| phase::which_phase ItoSolver::getPhase | ( | ) | const |
Return phase.
- Returns
- Returns m_phase
◆ getPhi()
|
virtual |
Get the mesh data.
- Returns
- Returns m_phi
◆ getPlotVariableNames()
|
virtual |
Get output plot names.
- Returns
- Returns a string of all variables that this solver can add to plot files.
◆ getRealm()
|
virtual |
Get the realm where this solver is registered.
- Returns
- m_realm
◆ getRegridParticles()
|
virtualnoexcept |
Get the reduced holder the bulk particles ride across a regrid in.
Only meaningful between preRegrid() and regrid(); the bulk ItoParticle container is empty over that window, and this is where its particles actually are. Exposed for load balancers that need to count or trial-regrid the population between those two calls – see BrownianWalkerStepper::loadBalanceBoxesParticles(). Reading getParticles(Bulk) there instead yields zero loads and a valid but unbalanced layout, with nothing to indicate anything went wrong.
- Returns
- The reduced-particle regrid holder.
◆ getSpecies()
|
virtual |
Get the species.
- Returns
- Returns m_species
◆ getVelocityFunction() [1/2]
|
virtual |
Get cell-centered velocity mesh data.
- Returns
- m_velocityFunction
◆ getVelocityFunction() [2/2]
|
virtual |
Get cell-centered velocity mesh data.
- Returns
- m_velocityFunction
◆ initialData()
|
virtual |
Set the initial data.
This will add the initial particles and deposit them.
◆ interpolateDiffusion() [1/2]
|
virtual |
Interpolate the diffusion field to the particle positions.
This computes D_p = Df(X_p) where Df is the diffusion field on the mesh.
◆ interpolateDiffusion() [2/2]
|
protectedvirtual |
Interpolate the diffusion field to the particle positions.
This computes D_p = Df(X_p) where Df is the diffusion field on the mesh.
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
◆ interpolateDiffusionGradient() [1/2]
|
virtual |
Interpolate the mesh diffusion gradient onto the particles' scratch vector storage.
This computes (grad D)(X_p) and writes it to the ItoParticle scratch vector columns, from which the caller adds dt*(grad D) to the particle displacement. The scratch columns are set to zero when the solver is not diffusive or the drift correction is disabled, so callers may add the term unconditionally. Requires a preceding call to computeDiffusionGradient().
◆ interpolateDiffusionGradient() [2/2]
|
virtual |
Interpolate the mesh diffusion gradient onto the particles' scratch vector storage, on one patch.
This computes (grad D)(X_p) and writes it to the ItoParticle scratch vector columns. Requires a preceding call to computeDiffusionGradient(). Public because the time steppers call it per patch, from inside their own OpenMP loops over boxes.
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
◆ interpolateMobilities()
|
virtual |
Interpolate mobilities.
This will switch between the two ways of computing the particle mobility.
◆ interpolateMobilitiesDirect()
|
protectedvirtualnoexcept |
Directly interpolate mobilities. Interpolates for all particles in the specified grid patch.
- Parameters
-
[in] a_lvl Grid level. [in] a_dit Grid index.
◆ interpolateMobilitiesVelocity()
|
protectedvirtualnoexcept |
Interpolate mobilities through the velocity. Interpolates for all particles in the specified grid patch.
- Parameters
-
[in] a_lvl Grid level. [in] a_dit Grid index. [in] a_velocityMagnitude Velocity magnitude.
◆ interpolateVelocities() [1/2]
|
virtual |
Interpolate the particle velocities.
This will compute the particle velocities as v = mu * V(Xp) where mu is the particle mobility and V(Xp) is the interpolation of m_velocityFunction to the particle position.
◆ interpolateVelocities() [2/2]
|
virtual |
Interpolate the particle velocities.
This will compute the particle velocities as v = mu * V(Xp) where mu is the particle mobility and V(Xp) is the interpolation of m_velocityFunction to the particle position.
- Parameters
-
[in] a_lvl Grid level [in] a_dit Grid index
◆ intersectParticles() [1/3]
|
virtual |
Do boundary intersection tests.
This will intersect the particles in the "bulk" particles data holder with the domain faces and EBs. If a particle crossed the EB it will be put into the "EB" particle data holder and likewise for the particles that crossed the domain side.
- Parameters
-
[in] a_ebIntersection Enum for switching between various types of intersection tests. [in] a_deleteParticles If true, the origin particle will also be removed from the bulk particle data holder. [in] a_nonDeletionModifier Optional input argument for letting the user manipulate particles that were intersected but not deleted
- Note
- This will call the other version with WhichContainer::Bulk, WhichContainer::EB, and WhichContainer::Domain.
◆ intersectParticles() [2/3]
|
virtual |
Do boundary intersection tests.
This will intersect the particles in the a_particles data holder with the domain faces and EBs. If a particle crossed the EB it will be put into the a_eb_particles particle data holder and likewise for the particles that crossed the domain side.
- Parameters
-
[in] a_particles Which particle container to use for the "active" particles [in] a_ebParticles Which particle container to put the EB particles [in] a_domainParticles Which particle container to put the domain particles [in] a_ebIntersection Enum for switching between various types of intersection tests. [in] a_deleteParticles If true, the origin particle will also be removed from the bulk particle data holder. [in] a_nonDeletionModifier Optional input argument for letting the user manipulate particles that were intersected but not deleted
- Note
- This will look up the ParticleContainer and call the other version.
◆ intersectParticles() [3/3]
|
virtual |
Do boundary intersection tests.
This will intersect the particles in the a_particles data holder with the domain faces and EBs. If a particle crossed the EB it will be put into the a_eb_particles particle data holder and likewise for the particles that crossed the domain side.
- Parameters
-
[in] a_particles Which particle container to use for the "active" particles [in] a_ebParticles Which particle container to put the EB particles [in] a_domainParticles Which particle container to put the domain particles [in] a_ebIntersection Enum for switching between various types of intersection tests. [in] a_deleteParticles If true, the origin particle will also be removed from the bulk particle data holder. [in] a_nonDeletionModifier Optional input argument for letting the user manipulate particles that were intersected but not deleted
◆ invalidateParticleIDs()
|
protected |
Set every particle id in a reduced-particle container to ParticleSoA::s_invalidID.
Run by mergeLite() after the whole-container methods, whose ids come from a rank-local counter that restarts every drain round. Those are merge scratch, not particle identity, and are indistinguishable from real ids downstream – where they would reach H5Part output. "No id" is the honest answer for a particle a merge produced, and is what an append()-built particle carries.
- Parameters
-
[in,out] a_particles Container whose id column is reset.
◆ isDiffusionGradientDrift()
|
virtualnoexcept |
Check if the grad(D) drift correction is enabled.
- Returns
- Returns m_diffusionGradientDrift.
◆ isDiffusive()
|
virtual |
Check if solver is diffusive.
- Returns
- Returns m_isDiffusive
◆ isMobile()
|
virtual |
Check if solver is mobile.
- Returns
- Returns m_isMobile
◆ kdWeightMedianCellWidths()
|
protectednoexcept |
Turn ItoSolver.kd_partition (and, for 'hybrid', ItoSolver.kd_hybrid_leaf_dx) into the single crossover length every kd tree build takes.
'weight' and 'count' are the two limits of the size-dependent rule – a crossover above any node's size and one below every node's size – so all three settings reduce to one number and the cell, patch and AMR builds read the same knob.
- Returns
- Node size, in cell widths, at or below which a node splits at the weight median.
◆ makeSuperparticles() [1/4]
|
virtual |
Make superparticles for a full container, merging to the solver's configured target.
The usual entry point: the target is ItoSolver.particles_per_cell and the method is ItoSolver.merge_method, so a caller that has no opinion about either does not have to carry one.
- Parameters
-
[in] a_container Which container to repartition into new superparticles.
◆ makeSuperparticles() [2/4]
|
virtual |
Make superparticles for a full container – this is the AMR version that users will usually call.
- Parameters
-
[in] a_container Which container to repartition into new superparticles [in] a_particlesPerCell Target number of particles per cell. Vector indicates grid levels.
◆ makeSuperparticles() [3/4]
|
virtual |
Make superparticles with an explicitly chosen method, ignoring the configured merge_method.
Lets a caller run a different method than the solver's own (e.g. a stepper choosing a regrid-time merge). Routes through mergeLite(); ParticleMergeMethod::None is a no-op.
- Parameters
-
[in] a_container Which container to repartition. [in] a_particlesPerCell Target particle count per cell (per-level; the last entry applies to any finer level). [in] a_method The merge method to run.
◆ makeSuperparticles() [4/4]
|
virtual |
Make superparticles for a full container – this is the AMR version that users will usually call.
- Parameters
-
[in] a_container Which container to repartition into new superparticles [in] a_particlesPerCell Target number of particles per cell
◆ mergeKDCell()
|
protected |
Cell-based merge: partition each cell's particles with a kd tree and reduce every leaf to one particle.
Two independent choices, both taken from the input script. ItoSolver.kd_partition picks the split rule: the weight median divides a node so the halves carry near-equal weight, dividing a particle when it must, which equalizes the merged weights; the count median divides on particle count and never divides a particle, so it creates none but leaves the weights uneven; hybrid takes the count median down to ItoSolver.kd_hybrid_leaf_dx cell widths and the weight median below that. ItoSolver.kd_placement picks where a leaf's particle goes: at the leaf's weighted centroid, at one of the leaf's own particles drawn with probability proportional to weight, or at a uniformly random point in the leaf's bounding box. The centroid keeps a leaf's mean position and discards its spread, so repeated merges contract the sub-cell distribution onto a lattice of leaf centres; the other two placements avoid that, and sampling additionally inherits a position that one of the original particles occupied.
- Parameters
-
[in,out] a_particles Particles to merge. [in] a_particlesPerCell Target number of particles per cell (one value, or one per level).
◆ mergeKDImpl()
|
protected |
Whole-container merge: whole-patch kd-tree build – shared implementation behind kd_patch and kd_amr with kd_amr_boundary = carve.
A single, non-iterative pass: no drain loop, and no nn_iterate/nn_fallback/ nn_max_cell_dist equivalents, since there is no configurable search radius or convergence loop. With a_enableBoundaryCarve the merge fills a width-1 particle ghost mask (which must be registered on this realm) and arbitrates leaves straddling a patch boundary; without it the merge is patch-local – no ghosts, no communication, and a cell straddled by two patches is reduced by each patch independently. Needs no cell sorting. Uses a single crowding threshold – the coarsest level's a_particlesPerCell entry. Drains over-full cells only; mergeLite() splits afterwards.
- Parameters
-
[in,out] merge Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count (only the first entry is used). [in] a_enableBoundaryCarve True to fill ghosts and run the carve tier, false for the patch-local merge.
◆ mergeKDSkinNn()
|
protected |
Whole-container merge: kd-tree with a nearest-neighbour skin (kd_amr_boundary = nn).
Same tree build and per-cell quota as mergeKDImpl(), but the boundary tier is the nearest-neighbour pair merge instead of the carve arbitration. The particles are split across two containers: ParticleManagement::mergeKDInterior() commits every leaf holding no ghost into one, and what is left – the contested skin – is drained from the other by ParticleManagement::mergeNearestNeighborsOneCell(), whose search radius is fixed at Chebyshev cell distance 1 and so matches the width-1 halo exactly. The skin tier drains each cell to what remains of its target after the interior results are counted against it, so the two tiers share one budget. Fills a width-1 particle ghost mask itself, which must be registered on this realm. Tuned by nn_iterate/nn_fallback/nn_max_rounds, shared with nn_amr; nn_max_cell_dist does not apply. Drains over-full cells only; mergeLite() splits afterwards.
- Parameters
-
[in,out] merge Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count (only the first entry is used).
◆ mergeLite()
|
protected |
Run one merge method over an already-extracted reduced-particle container.
The single place that knows the shape of each merge method, so that no caller has to. Two shapes exist and they are not interchangeable:
- cell-based (kd_cell, reinitialize, external): reduce each cell to at most its per-level target, refilling only within that same per-cell budget. These must NOT be followed by the container-wide split.
- whole-container (kd_patch, kd_amr, nn_amr): drain over-full cells against one crowding threshold for the whole hierarchy, then split under-full cells back up to it. These MUST split, and they mint scratch ids that are invalidated afterwards. ParticleMergeMethod::None does neither – not even the split, which would otherwise refill every under-full cell in the domain at every regrid. Getting that wrong is silent: nothing fails, the population simply grows.
- Parameters
-
[in,out] a_particles Reduced-particle container to merge in place. [in] a_particlesPerCell Target particle count per cell (per-level for the cell-based methods; the whole-container methods use the first entry only). [in] a_method Which merge method to run.
◆ mergeNnPairOneCell()
|
protected |
Whole-container merge: distributed nearest-neighbour pair merge, per-cell PointCloudBVH search.
As mergeNnPairSearch(), but the merge distance is structurally fixed at Chebyshev cell distance 1 (own cell and Moore-adjacent neighbours only), so nn_max_cell_dist is not honoured by this method. Requires a width-1 particle ghost mask registered on this realm. Drains over-full cells only; mergeLite() splits afterwards.
- Parameters
-
[in,out] merge Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count (only the first entry is used).
◆ mergeNnPairSearch()
|
protected |
Whole-container merge: distributed nearest-neighbour pair merge – shared implementation behind nn_search = tree and nn_search = hash.
Whole-container, cross-patch/cross-rank AMR merge. Identical in every respect between the two backends (callbacks, id allocation, drain loop); only the ParticleManagement::mergeNearestNeighborsTree()/mergeNearestNeighborsHash() call inside the drain loop differs, selected at compile time via Backend. Requires the particle ghost mask registered on this realm (see registerOperators()); it does its own ghost fill and needs no cell sorting. Uses a single crowding threshold – the coarsest level's a_particlesPerCell entry. Drains over-full cells only; mergeLite() splits afterwards.
- Template Parameters
-
Backend Which point-cloud index to search with. Only NNSearch::Tree and NNSearch::Hash are instantiated; NNSearch::OneCell is mergeNnPairOneCell(), which is a different algorithm.
- Parameters
-
[in,out] merge Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count (only the first entry is used).
◆ mergeReinitialize()
|
protected |
Cell-based merge: redistribute each cell's physical particles into near-equal integer weights at random cell positions.
All output particles carry the same weight-averaged energy. Requires integer weights. Honours the per-level target.
- Parameters
-
[in,out] a_particles Reduced-particle container to repartition. [in] a_particlesPerCell Target particle count per cell (per-level).
◆ mirrorPass()
| void ItoSolver::mirrorPass | ( | EBAMRCellData & | a_phi, |
| const ParticleContainer< P, Traits > & | a_particles, | ||
| const DepositionType | a_deposition, | ||
| const CoarseFineDeposition | a_coarseFineDeposition, | ||
| const Strength | a_strength | ||
| ) | const |
Add the mirrored contribution of the band particles to an already-deposited field.
Deposition divides by dx^D and never by kappa, so a cut cell holds kappa*n where the fluid solvers hold n. This pass removes that by additionally depositing the cloud of each band particle's image, reflected across the embedded boundary – a kernel density estimate of the even extension of the density. Under this option, and only this one, a cut cell therefore holds n rather than kappa*n.
Runs after the real deposit and adds to it. Images are built from the VALID holder only: the halo coarse-fine cores copy particles into a mask holder, so building from that would produce a second image for the same particle – the double count that issue #29 fell into. All three cores restore the valid holder before returning, so running afterwards is safe; the constraint is which holder, not when.
- Parameters
-
[in,out] a_phi Field to add the mirrored contribution to. [in] a_particles Particles whose images are deposited. [in] a_deposition Deposition kernel, the same one the real deposit used. [in] a_coarseFineDeposition Coarse-fine strategy, likewise. [in] a_strength Per-particle strength: leaf.weight(i) from the depositWeight funnel, the caller's gatherer from the depositGathered one. Both funnels must call this, or the mapping silently applies to only some of the solver's fields.
- Template Parameters
-
P Payload type of the container. Traits Column descriptor for the payload. Strength Callable (const ParticleSoA<P, Traits>&, std::size_t) -> Real.
◆ operator=()
Default move assignment operator.
- Returns
- Reference to this object
◆ organizeParticlesByCell()
|
virtual |
Sort the input particle container by cell.
- Parameters
-
[in] a_container Container to be sorted.
◆ organizeParticlesByPatch()
|
virtual |
Sort the input particle container by patch.
- Parameters
-
[in] a_container Container to be sorted.
◆ preRegrid()
|
virtual |
Perform pre-regrid operations.
- Parameters
-
[in] a_lbase Coarsest level that changed during regrid. [in] a_oldFinestLevel Finest grid level before the regrid operation.
- Note
- This caches the bulk particles.
◆ randomDirection()
|
inline |
Draw a random direction in N-dimensional space.
We use the algorithm by Marsaglia (1972).
- Returns
- Return value
◆ randomGaussian()
|
inline |
Draw a random N-dimensional Gaussian number from a normal distribution with zero with and unit standard deviation.
- Note
- The distribution is truncated at m_normalDistributionTruncation – values above that threshold will be replaced by m_normalDistributionTruncation.
- Returns
- Return value
◆ rebuildFromMergeContainer()
|
protected |
Rebuild a container's ItoParticles from the reduced particles.
Rebuilds into the same patch (no remap); velocity/mobility/diffusion default to zero and are recomputed from the field before use. particleID is carried across. Each reduced leaf's arena is released as its ItoParticle copy is built. Leaves a_container patch-organized.
- Parameters
-
[in] a_container Which container to rebuild into. [in,out] a_merge The reduced-particle container to consume.
◆ redistributeAMR()
|
protectedvirtual |
Redistribute mass in an AMR context.
We will have deposited particles into each cell, i.e. phi_i = m_i/dx^3. To obtain the true density in an EB context we need to divide by kappa such that phi_i = m_i/(kappa_i*dx^3). Unfortunately, this is numerically unstable because kappa_i can be arbitrarily small. We can set the density as phi_i = m_i/dx^3 but we will be missing a mass m_i*(1-kappa_i) from the cell. This mass can be smooshed into neighboring cells such as to make the total scheme conservative. As an option, we can also use a "non-conservative" divergence but the scheme is not guaranteed to be non-negative. All of this is just to say that we take the mass that fell inside the EB and put it back into the domain.
- Parameters
-
[in,out] a_phi Quantity to be redistributed.
◆ registerOperators()
|
virtual |
Register operators.
This will register the required operators for running this class.
◆ regrid()
|
virtual |
Regrid this solver.
- Parameters
-
[in] a_lmin Coarsest level where grids did not change. [in] a_oldFinestLevel Finest AMR level before the regrid. [in] a_newFinestLevel Finest AMR level after the regrid.
◆ remap()
|
virtual |
Remap all particles in the input container.
- Parameters
-
[in] a_container Particle container
◆ removeCoveredParticles() [1/3]
|
virtual |
Remove particles that are inside the EB.
- Parameters
-
[in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary.
Calls the other version with m_particles.
- Parameters
-
[in] a_representation Representation
◆ removeCoveredParticles() [2/3]
|
virtual |
Remove particles that are inside the EB.
- Parameters
-
[in] a_particles Particles to remove. [in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary. [in] a_representation Representation
◆ removeCoveredParticles() [3/3]
|
virtual |
Remove particles that are inside the EB.
- Parameters
-
[in] a_container Which particle container to remove particles from [in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary.
- Note
- Calls the other version with ParticleContainer = m_particles.at(a_container)
- Parameters
-
[in] a_representation Representation
◆ setAmr()
|
virtual |
◆ setComputationalGeometry()
|
virtual |
Set computational geometry.
- Parameters
-
[in] a_computationalGeometry Computational geometry.
◆ setDiffusionFunction()
|
virtual |
Utility function – set a constant diffusion coefficient.
- Parameters
-
[in] a_diffusionCoefficient Diffusion coefficient
◆ setParticleCellMerger()
|
virtualnoexcept |
Set the user-supplied per-cell particle merger used by merge_method = external.
The built-in merge methods build their own per-cell merger internally; this one is used only when merge_method = external, applied cell-by-cell by makeSuperparticles().
- Note
- The merger runs on ItoMergeParticle, not ItoParticle: every merge in this solver operates on the reduced particle, and a per-cell merger sees exactly the columns a merge is entitled to change (position, weight, energy). Out-of-tree mergers written against ItoParticle break at compile time.
- Parameters
-
[in] a_particleCellMerger Per-cell particle merger.
◆ setParticleDiffusion()
|
virtual |
Sets diffusion coefficient for all particles.
- Parameters
-
[in] a_diffCo Particle diffusion value.
◆ setParticleMobility()
|
virtual |
Sets mobility coefficient for all particles.
- Parameters
-
[in] a_mobility Particle mobility.
◆ setPhase()
|
virtual |
Set phase where the particles will live.
- Parameters
-
[in] a_phase Phase
◆ setRealm()
|
virtual |
Set the realm where this solver will live.
- Parameters
-
[in] a_realm Realm name.
◆ setSpecies()
|
virtual |
Set the species.
- Parameters
-
[in] a_species Species to be solved for.
◆ setTime()
|
virtual |
Set the time for this solver.
- Parameters
-
[in] a_step Time step number [in] a_time Time (in seconds) [in] a_dt Time step increment
- Note
- This sets m_step=a_step, m_time=a_time, m_dt=a_dt
◆ setVelocityFunction()
|
virtual |
Utility function – set a constant velocity.
- Parameters
-
[in] a_velocity Velocity
◆ setVerbosity()
|
virtual |
Set verbosity level for this solver.
- Parameters
-
[in] a_verbosity Verbosity level.
◆ splitFromMergeContainer()
|
protected |
Split every under-full cell up to the target count.
The whole-container merge/drain phase only reduces over-full cells; this brings cells below the target back up to it via greedy heaviest-particle splitting. Called only from mergeLite(), and only for the methods whose shape calls for it – see there.
- Parameters
-
[in,out] a_merge Reduced-particle container to split (cell-sorted internally). [in] a_numParticlesPerCellThresh Target particle count per cell.
◆ transferCoveredParticles() [1/3]
|
virtual |
Transfer particles that are covered (within a_tol distance from EB) to another container.
Calls the other version with m_particles and m_coveredParticles
- Parameters
-
[in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary. [in] a_representation Representation
◆ transferCoveredParticles() [2/3]
|
virtual |
Transfer particles that are inside the EB to another container.
- Parameters
-
[in] a_particlesFrom Which particle container to transfer particles from [in] a_particlesTo Which particle container to move particles into [in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary. [in] a_representation Representation
◆ transferCoveredParticles() [3/3]
|
virtual |
Transfer particles that are covered (within a_tol distance from EB) to another container.
- Parameters
-
[in] a_containerFrom Which particle container to transfer particles from [in] a_tol Tolerance – removes particles if they are less than a_tol*dx away from the boundary. [in] a_containerTo Container to [in] a_representation Representation
◆ updateDiffusion() [1/2]
|
virtual |
Update mobilities parametrically from the particle energy.
This calls the diffusion function implemented by ItoSpecies. The particle diffusion is set D = f(p.energy()) where f is the diffusion function in ItoSpecies
◆ updateDiffusion() [2/2]
|
protectedvirtual |
Update mobilities parametrically from the particle energy.
This calls the diffusion function implemented by ItoSpecies. The particle diffusion is set D = f(p.energy()) where f is the diffusion function in ItoSpecies
- Parameters
-
[in] a_level Grid level [in] a_dit Grid index
◆ updateMobilities() [1/2]
|
virtual |
Update mobilities parametrically from the particle energy.
This calls the mobility function implemented by ItoSpecies. The particle mobility is set mu = f(p.energy()) where f is the mobility function in ItoSpecies
◆ updateMobilities() [2/2]
|
protectedvirtual |
Update mobilities parametrically from the particle energy.
This calls the mobility function implemented by ItoSpecies. The particle mobility is set mu = f(p.energy()) where f is the mobility function in ItoSpecies
- Parameters
-
[in] a_level Grid level [in] a_dit Grid index
◆ writeData()
|
protectedvirtualnoexcept |
Write data to output. Convenience function.
- Parameters
-
[in,out] a_output Output data holder. [in] a_data Data to write. [in] a_outputRealm Realm where a_output belongs [in] a_level Grid level [in] a_interpToCentroids If true, a_data will be interpolated to cell centroids before writing to a_output. [in] a_interpGhost If true, interpolate ghost cells [in] a_comp Comp
◆ writePlotData()
|
virtualnoexcept |
Write plot data.
- Parameters
-
[in,out] a_output Output data holder. [in] a_outputRealm Realm where a_output belongs [in] a_level Grid level
- Note
- This will write the plot data in this solver to a_output, starting on a_comp
- Parameters
-
[in] a_comp Comp
Member Data Documentation
◆ m_className
|
protected |
Class name.
ItoSolver for parent class – derived classes might be named something else.
◆ m_diffusionGradient
|
protected |
Cell-centered gradient of m_diffusionFunction, used for the grad(D) drift correction.
Allocated only when the solver is diffusive and m_diffusionGradientDrift is true; otherwise this is a bare pointer holder. Recomputed from m_diffusionFunction by computeDiffusionGradient(), so it carries no state across a regrid and is never checkpointed.
◆ m_diffusionGradientDrift
|
protected |
If true, grad(D) is added to the particle drift.
Set from ItoSolver.diffusion_grad_drift. An Ito-interpretation Euler-Maruyama update with a drift of v alone transports the flux v*n - grad(D*n); adding grad(D) to the drift makes it transport v*n - D*grad(n) instead, which is the flux CdrSolver integrates. The two coincide only where D is constant in space.
◆ m_irregularDeposition
|
protected |
How the cut cells are treated when depositing.
One selector replaces the former irr_ngp_deposition/redistribute/blend_conservation triple; see CD_IrregularDeposition.H for why these must not be independent flags.
◆ m_kdAmrBoundary
|
protected |
kd_amr: how leaves that touch a patch or rank boundary are resolved.
ItoSolver.kd_amr_boundary. Selects between mergeKDImpl() (carve) and mergeKDSkinNn() (nn).
◆ m_kdHybridLeafDx
|
protected |
kd_partition = hybrid: node size, in cell widths, at or below which the split plane switches from the count median to the weight median.
ItoSolver.kd_hybrid_leaf_dx. Only meaningful for KDPartition::Hybrid – 'weight' and 'count' are the two limits of the same rule and ignore this. Larger values apply the weight median to bigger nodes, giving more uniform super-particle weights at some cost to how evenly leaves are apportioned between cells.
◆ m_kdMergeCellHistogram
|
protected |
Per-cell occupancy scratch for the kd merges (see ParticleManagement::mergeKDCarve).
Owned here, not by the merge, so the allocation happens once per regrid rather than once per merge call. Allocated and released with the other mesh fields, in allocate()/regrid() and preRegrid() respectively.
◆ m_kdPartition
|
protected |
kd_cell/kd_patch/kd_amr: how each node is divided into two children.
ItoSolver.kd_partition. Turned into a crossover length by kdWeightMedianCellWidths().
◆ m_kdPlacement
|
protected |
kd_cell/kd_patch/kd_amr: where the particle a leaf reduces to is placed.
ItoSolver.kd_placement. See mergeKDCell() and mergeKDImpl().
◆ m_kdSplitPlacement
|
protected |
Where the pieces of a split particle are placed.
ItoSolver.split_placement. 'center' reproduces the parent's position, which keeps the merge from moving any mass but leaves the pieces indistinguishable; 'jitter' and 'cell' spread them so a cell's particle count and its DISTINCT-position count do not diverge.
◆ m_mergeMethod
|
protected |
The configured merge method (which scope the merge groups particles over).
Set by parseParticleMerger() from ItoSolver.merge_method. makeSuperparticles() dispatches on this to run the right algorithm. Defaults to KdCell (the default merge_method).
◆ m_mirrorImages
|
mutableprotected |
Reflected images of the band particles, for IrregularDeposition::Mirror.
Rebuilt from scratch by every mirror pass and cleared at its START rather than its end, so that a pass that aborts partway cannot leak images into the next deposit. Holds no identity: ParticleSoA::append(pos, weight) leaves the metadata columns invalid, nothing in remap() reads them, and an image is not a particle anyone can refer to.
- Note
- Allocated per solver here rather than shared on the realm. Sharing one container across every solver on a (realm, phase) would need it to live on PhaseRealm, which in turn needs the realm name, minimum block size, level tiles and valid cells that ParticleContainer::define takes and PhaseRealm does not hold – plus an in-flight assertion, because a shared mutable scratch is only safe while solvers deposit serially. Owning one per solver needs none of that, at the cost of one container per species.
◆ m_mirrorScratch
|
mutableprotected |
Mesh scratch the mirror images deposit into, before being added to the real field.
One component, because EBAMRParticleMesh::depositWeight asserts on that.
- Note
- The images CANNOT be deposited straight into the solver's field, and the reason is not just that every AMR deposit opens by zeroing its target. The level exchange is a reversed copier with an add op – the ghost region is the source and the owner's valid region the destination – and nothing writes those ghosts back to zero afterwards. A second deposit into the same field would fold the first pass's ghost content into the valid region again, silently double counting in proportion to each patch's ghost share.
◆ m_nnIterate
|
protected |
nn_amr: iterate the local trivial tier to convergence within each round.
Forwarded to ParticleManagement::mergeNearestNeighborsTree()/mergeNearestNeighborsOneCell()/ mergeNearestNeighborsHash(). Also read by kd_amr with kd_amr_boundary = nn, whose skin tier is a nearest-neighbour merge.
◆ m_nnMaxRounds
|
protected |
nn_amr: maximum number of drain rounds run per makeSuperparticles() call.
Each round merges nearest-neighbor pairs and roughly halves an over-full cell's surplus; the loop also stops early once a round merges nothing. This caps the round count so the cost stays bounded and predictable rather than running to full convergence. Also read by kd_amr with kd_amr_boundary = nn.
◆ m_nnSearch
|
protected |
nn_amr: which spatial index the neighbour search is backed by.
ItoSolver.nn_search.
◆ m_normalDistributionTruncation
|
protected |
Truncation value for normal distribution.
This is used when drawing numbers from the Gaussian distribution, replacing all values above m_normalDistributionTruncation by m_normalDistributionTruncation.
◆ m_particlesPerCell
|
protected |
Target number of computational particles per cell, per AMR level.
Set by parseParticleMerger() from ItoSolver.particles_per_cell. The solver owns this because the solver is where merging happens – it is the target every merge reduces to, the count initialData() seeds the bulk container at, and (through getParticlesPerCell()) the number a particle-count load estimate has to assume. A time stepper still owns when to merge during a run (ItoKMCStepper.merge_interval); it no longer owns what to merge to.
Per-level, for compatibility with the ItoKMCStepper key it replaces. Only the cell-based methods honour it per level; the whole-container methods use one crowding threshold for the whole hierarchy and read entry 0, so parseParticleMerger() aborts on a non-uniform vector rather than silently truncating it.
◆ m_regridMergeMethod
|
protected |
Which merge method to run inside ItoSolver::regrid(), or nullopt for "whatever merge_method says".
Set by parseParticleMerger() from ItoSolver.regrid_superparticles. A separate knob from merge_method because the two are genuinely independent: the regrid merge runs once per regrid on a population that has just been redistributed, and a run may reasonably want a cheaper (or no) method there than it uses per step. ParticleMergeMethod::None turns the regrid merge off; the extract/rebuild round-trip still happens, since preRegrid() has already reduced the particles by then.
◆ m_regridParticles
|
protected |
The bulk particles, in reduced form, between preRegrid() and regrid().
At a de-refining regrid 2^D fine cells collapse into one coarse cell, so between the redistribution and the merge each rank transiently holds up to 2^D times the target particles per cell. This container is what that spike is held in: preRegrid() extracts the bulk container into it, the redistribution and load balancing happen on it, and regrid() merges it and only then rebuilds ItoParticles. 53 B per particle in 3-D instead of 149 B, and the merge runs before the population is ever materialised at the larger size.
Bulk only. The EB/Domain/Source/Covered/Scratch containers keep the plain ParticleContainer::preRegrid() path – they are small, none of them is merged, and Scratch is never populated.
Live only across a regrid: regrid() releases it before returning. It is a member rather than a local because preRegrid() and regrid() are separate calls with the load-balancing phase between them, and because BrownianWalkerStepper's particle load balancer has to count it.
The documentation for this class was generated from the following files:
- Source/ItoDiffusion/CD_ItoSolver.H
- Source/ItoDiffusion/CD_ItoSolver.cpp
- Source/ItoDiffusion/CD_ItoSolverImplem.H
